
transformers
这是Hugging Face推出的机器学习模型定义框架,支持文本、音视频、多模态模型的训练与推理,适配主流AI开发工具链。
这个项目值得继续研究吗?
这是Hugging Face推出的机器学习模型定义框架,支持文本、音视频、多模态模型的训练与推理,适配主流AI开发工具链。
- 解决什么问题
- 企业落地AI应用时,常面临不同类型大模型适配复杂、训练与推理工具链互不兼容、从零训练模型算力成本高、重复造轮子浪费研发资源的痛点。
- 适合什么团队
- 需要接入或自研大模型开发AI应用的企业技术团队,覆盖NLP、计算机视觉、音视频处理、多模态应用等相关业务线。
- 使用前注意
- 部署需Python 3.10+、PyTorch 2.5+运行环境,源码安装的最新版本可能不稳定,本库不是模块化工具,采用Apache-2.0许可可商用。
本页用于缩短初步筛选时间,不构成技术、采购或法律结论。 正式使用前请在真实业务数据上验证,并以官方说明与许可证为准。
从官方资料看清能力、部署与采用边界
以下内容依据项目公开 README 或模型卡翻译整理,代码、命令和产品名保持原样。
项目定位
Transformers是Hugging Face推出的机器学习模型定义框架,是AI开发生态的核心枢纽,统一了各类前沿模型的定义标准,只要是适配该框架的模型,就能兼容市面上绝大多数主流训练框架、推理引擎以及周边建模库。目前Hugging Face Hub上已有超过100万个适配Transformers的预训练模型,可直接调取使用。
核心能力
- 全模态任务覆盖:支持文本、计算机视觉、音频、视频、多模态五大类AI任务,涵盖文本生成、语音识别、图像分类、视觉问答等主流应用场景。
- 低门槛统一API:提供高层封装的Pipeline接口,仅需几行代码即可完成模型调用,自动处理输入预处理、输出后处理流程,大幅降低模型使用门槛。
- 全生态工具兼容:适配Axolotl、Unsloth、DeepSpeed等主流训练框架,vLLM、SGLang等推理引擎,以及llama.cpp、mlx等周边建模库,无需额外适配即可对接现有开发工具链。
- 跨框架灵活切换:支持同一个模型在PyTorch、JAX、TF2.0不同框架之间自由迁移,企业可根据训练、评估、生产部署不同阶段的需求选择合适的框架。
- 成本优化:无需从零训练模型,直接使用已公开的预训练模型即可落地业务,大幅降低算力投入和研发成本。
典型使用方式
所有场景的调用逻辑基本一致,只需指定任务类型和对应的预训练模型即可快速跑通:
- 文本生成:指定text-generation任务和对应大模型,传入提示词即可获得生成结果,模型会自动下载到本地缓存可重复使用,示例代码如下:
from transformers import pipeline
pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")- 智能对话:和文本生成逻辑一致,只需传入结构化的对话历史即可获得模型回复,也可通过transformers serve启动服务后,直接用命令行transformers chat 模型名和模型对话。
- 语音识别:指定automatic-speech-recognition任务和语音模型,传入音频文件或链接即可转写为文字。
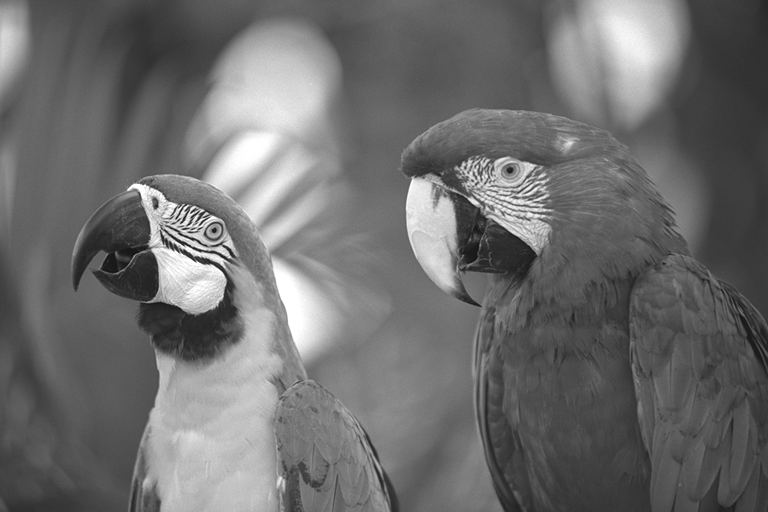
- 图像分类:指定image-classification任务和图像模型,传入图片即可返回分类标签和置信度。
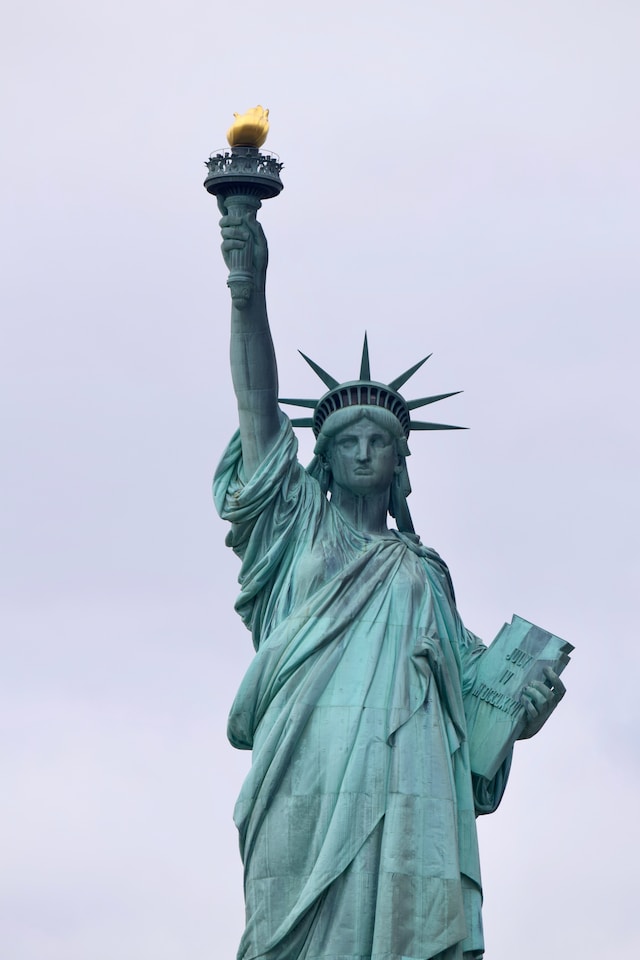
- 视觉问答:指定visual-question-answering任务和多模态模型,同时传入图片和问题即可获得对应答案。
部署要求
- 运行环境要求:Python 3.10及以上版本,PyTorch 2.5及以上版本。
- 安装方式:推荐先通过venv或uv创建虚拟环境,再通过pip或uv安装官方正式版;如果需要使用最新功能可安装源码版本,但源码版本可能不稳定,遇到问题可提交官方Issue反馈。
许可证与采用建议
本项目采用Apache-2.0许可证,企业可自由修改、商用,无需额外授权。适合需要快速落地各类AI应用的企业使用,可大幅减少模型适配、工具链对接的研发投入,降低从零训练模型的算力成本。如果你的团队需要高度模块化自定义底层AI框架,则不适合使用本项目。
官方资料与来源
- audio
- deep-learning
- deepseek
- gemma
- glm
- hacktoberfest
- llm
- machine-learning
- model-hub
- natural-language-processing
- nlp
- pretrained-models
## Installation

Transformers works with Python 3.10+, and [PyTorch](https://pytorch.org/get-started/locally/) 2.5+.

Create and activate a virtual environment with [venv](https://docs.python.org/3/library/venv.html) or [uv](https://docs.astral.sh/uv/), a fast Rust-based Python package and project manager.

```py
该片段来自项目 README,仅用于初步判断;实际部署请以官方文档为准。


核对上游原始说明节选
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
Copyright 2020 The HuggingFace Team. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the specific language governing permissions and limitations under the License. -->
English | 简体中文 | 繁體中文 | 한국어 | Español | 日本語 | हिन्दी | Русский | Português | తెలుగు | Français | Deutsch | Italiano | Tiếng Việt | العربية | اردو | বাংলা | فارسی | Română | Türkçe
State-of-the-art pretrained models for inference and training
Transformers acts as the model-definition framework for state-of-the-art machine learning with text, computer vision, audio, video, and multimodal models, for both inference and training.
It centralizes the model definition so that this definition is agreed upon across the ecosystem. transformers is the pivot across frameworks: if a model definition is supported, it will be compatible with the majority of training frameworks (Axolotl, Unsloth, DeepSpeed, FSDP, PyTorch-Lightning, ...), inference engines (vLLM, SGLang, TGI, ...), and adjacent modeling libraries (llama.cpp, mlx, ...) which leverage the model definition from transformers.
We pledge to help support new state-of-the-art models and democratize their usage by having their model definition be simple, customizable, and efficient.
There are over 1M+ Transformers model checkpoints on the Hugging Face Hub you can use.
Explore the Hub today to find a model and use Transformers to help you get started right away.
Installation
Transformers works with Python 3.10+, and PyTorch 2.5+.
Create and activate a virtual environment with venv or uv, a fast Rust-based Python package and project manager.
# venv
python -m venv .my-env
source .my-env/bin/activate
# uv
uv venv .my-env
source .my-env/bin/activate
Install Transformers in your virtual environment.
# pip
pip install "transformers[torch]"

# uv
uv pip install "transformers[torch]"
Install Transformers from source if you want the latest changes in the library or are interested in contributing. However, the latest version may not be stable. Feel free to open an issue if you encounter an error.
git clone https://github.com/huggingface/transformers.git
cd transformers

# pip
pip install '.[torch]'

# uv
uv pip install '.[torch]'
Quickstart
Get started with Transformers right away with the Pipeline API. The Pipeline is a high-level inference class that supports text, audio, vision, and multimodal tasks. It handles preprocessing the input and returns the appropriate output.
Instantiate a pipeline and specify model to use for text generation. The model is downloaded and cached so you can easily reuse it again. Finally, pass some text to prompt the model.
from transformers import pipeline

pipeline = pipeline(task="text-generation", model="Qwen/Qwen2.5-1.5B")
pipeline("the secret to baking a really good cake is ")
[{'generated_text': 'the secret to baking a really good cake is 1) to use the right ingredients and 2) to follow the recipe exactly. the recipe for the cake is as follows: 1 cup of sugar, 1 cup of flour, 1 cup of milk, 1 cup of butter, 1 cup of eggs, 1 cup of chocolate chips. if you want to make 2 cakes, how much sugar do you need? To make 2 cakes, you will need 2 cups of sugar.'}]
To chat with a model, the usage pattern is the same. The only difference is you need to construct a chat history (the input to Pipeline) between you and the system.
[!TIP]
You can also chat with a model directly from the command line, as long as transformers serve is running.
```shell
transformers chat Qwen/Qwen2.5-0.5B-Instruct
```
import torch
from transformers import pipeline

chat = [
    {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
    {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
]

pipeline = pipeline(task="text-generation", model="meta-llama/Meta-Llama-3-8B-Instruct", dtype=torch.bfloat16, device_map="auto")
response = pipeline(chat, max_new_tokens=512)
print(response[0]["generated_text"][-1]["content"])
Expand the examples below to see how Pipeline works for different modalities and tasks.
Automatic speech recognition
from transformers import pipeline

pipeline = pipeline(task="automatic-speech-recognition", model="openai/whisper-large-v3")
pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
Image classification
from transformers import pipeline

pipeline = pipeline(task="image-classification", model="facebook/dinov2-small-imagenet1k-1-layer")
pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
[{'label': 'macaw', 'score': 0.997848391532898},
 {'label': 'sulphur-crested cockatoo, Kakatoe galerita, Cacatua galerita',
  'score': 0.0016551691805943847},
 {'label': 'lorikeet', 'score': 0.00018523589824326336},
 {'label': 'African grey, African gray, Psittacus erithacus',
  'score': 7.85409429227002e-05},
 {'label': 'quail', 'score': 5.502637941390276e-05}]
Visual question answering
from transformers import pipeline

pipeline = pipeline(task="visual-question-answering", model="Salesforce/blip-vqa-base")
pipeline(
    image="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/idefics-few-shot.jpg",
    question="What is in the image?",
)
[{'answer': 'statue of liberty'}]
Why should I use Transformers?
- Easy-to-use state-of-the-art models:
- High performance on natural language understanding & generation, computer vision, audio, video, and multimodal tasks.
- Low barrier to entry for researchers, engineers, and developers.
- Few user-facing abstractions with just three classes to learn.
- A unified API for using all our pretrained models.
- Lower compute costs, smaller carbon footprint:
- Share trained models instead of training from scratch.
- Reduce compute time and production costs.
- Hundreds of model architectures with 1M+ pretrained checkpoints across all modalities.
- Choose the right framework for every part of a model's lifetime:
- Train state-of-the-art models in 3 lines of code.
- Move a single model between PyTorch/JAX/TF2.0 frameworks at will.
- Pick the right framework for training, evaluation, and production.
- Easily customize a model or an example to your needs:
- We provide examples for each architecture to reproduce the results published by its original authors.
- Model internals are exposed as consistently as possible.
- Model files can be used independently of the library for quick experiments.
When shouldn't I use Transformers?
- This library is not a modular tool
 优秘智能