rag ·
nomic-embed-text-v1.5
任务类型:sentence-similarity
# nomic-embed-text-v1.5: Resizable Production Embeddings with Matryoshka Representation Learning [Blog](https://www.nomic.ai/blog/posts/nomic-embed-text-v1) | [Technical Report](https://arxiv.org/abs/2402.01613) | [AWS SageMaker](https://aws.amazon.com/marketplace/seller-profile?id=seller-tpqidcj54zawi) | [Nomic Platform](https://atlas.nomic.ai) **Exciting Update!**: `nomic-embed-text-v1.5` is now multimodal! [nomic-embed-vision-v1.5](https://huggingface.co/nomic-ai/nomic-embed-vision-v1.5) is aligned to the embedding space of `nomic-embed-text-v1.5`, meaning any text embedding is multimodal! ## Usage **Important**: the text prompt *must* include a *task instruction prefix*, instructing the model which task is being performed. For example, if you are implementing a RAG application, you embed your documents as `search_document: ` and embed your user queries as `search_query: `. **Notice**: From transformers v5.5.0 and sentence transformers v5.3.0, `trust_remote_code=True` will no longer be necessary. This will only be possible with the text-only series as of now. ## Task instruction prefixes ### `search_document` #### Purpose: embed texts as documents from a dataset This prefix is used for embedding texts as documents, for example as documents for a RAG index. ```python from sentence_transformers import SentenceTransformer model = SentenceTransformer("nomic-ai/nomic-embed-text-v1.5") sentences = ['search_document: TSNE is a dimensionality reduction algorithm created by Laurens van Der Maaten'] embeddings = model.encode(sentences) print(embeddings) ``` ### `search_query` #### Purpose: embed texts as questions to answer This prefix is used for embedding texts as questions that documents from a dataset could resolve, for example as queries to be answered by a RAG application. ```python from sentence_transformers import SentenceTransformer model = SentenceTransformer("nomic-ai/nomic-embed-text-v1.5") sentences = ['search_query: Who is Laurens van Der Maaten?'] embeddings = model.encode(sentences) print(embeddings) ``` ### `clustering` #### Purpose: embed texts to group them into clusters This prefix is used for embedding texts in order to group them into clusters, discover common topics, or remove semantic duplicates. ```python from sentence_transformers import SentenceTransformer model = SentenceTransformer("nomic-ai/nomic-embed-text-v1.5") sentences = ['clustering: the quick brown fox'] embeddings = model.encode(sentences) print(embeddings) ``` ### `classification` #### Purpose: embed texts to classify them This prefix is used for embedding texts into vectors that will be used as features for a classification model ```python from sentence_transformers import SentenceTransformer model = SentenceTransformer("nomic-ai/nomic-embed-text-v1.5") sentences = ['classification: the quick brown fox'] embeddings = model.encode(sentences) print(embeddings) ``` ### Sentence Transformers ```python import torch.nn.functional as F from sentence_transformers import SentenceTransformer matryoshka_dim = 512 model = SentenceTransformer("nomic-ai/nomic-embed-text-v1.5") sentences = ['search_query: What is TSNE?', 'search_query: Who is Laurens van der Maaten?'] embeddings = model.encode(sentences, convert_to_tensor=True) embeddings = F.layer_norm(embeddings, normalized_shape=(embeddings.shape[1],)) embeddings = embeddings[:, :matryoshka_dim] embeddings = F.normalize(embeddings, p=2, dim=1) print(embeddings) ``` ### Transformers ```diff import torch import torch.nn.functional as F from transformers import AutoTokenizer, AutoModel def mean_pooling(model_output, attention_mask): token_embeddings = model_output[0] input_mask_expanded = attention_mask.unsqueeze(-1).expand(token_embeddings.size()).float() return torch.sum(token_embeddings * input_mask_expanded, 1) / torch.clamp(input_mask_expanded.sum(1), min=1e-9) sentences = ['search_query: What is TSNE?', 'search_query: Who is Laurens van der Maaten?'] tokenizer = AutoTokenizer.from_pretrained('bert-base-uncased') model = AutoModel.from_pretrained('nomic-ai/nomic-embed-text-v1.5') model.eval() encoded_input = tokenizer(sentences, padding=True, truncation=True, return_tensors='pt') + matryoshka_dim = 512 with torch.no_grad(): model_output = model(**encoded_input) embeddings = mean_pooling(model_output, encoded_input['attention_mask']) + embeddings = F.layer_norm(embeddings, normalized_shape=(embeddings.shape[1],)) + embeddings = embeddings[:, :matryoshka_dim] embeddings = F.normalize(embeddings, p=2, dim=1) print(embeddings) ``` The model natively supports scaling of the sequence length past 2048 tokens. To do so, ```diff - tokenizer = AutoTokenizer.from_pretrained('bert-base-uncased') + tokenizer = AutoTokenizer.from_pretrained('bert-base-uncased', model_max_length=8192) - model = AutoModel.from_pretrained('nomic-ai/nomic-embed-text-v1.5') + rope_parameters = {"rope_theta": 1000.0, "rope_type": "dynamic", "factor": 2.0} + model = AutoModel.from_pretrained('nomic-ai/nomic-embed-text-v1.5', rope_parameters=rope_parameters) ``` ### Transformers.js ```js import { pipeline, layer_norm } from '@huggingface/transformers'; // Create a feature extraction pipeline const extractor = await pipeline('feature-extraction', 'nomic-ai/nomic-embed-text-v1.5'); // Define sentences const texts = ['search_query: What is TSNE?', 'search_query: Who is Laurens van der Maaten?']; // Compute sentence embeddings let embeddings = await extractor(texts, { pooling: 'mean' }); console.log(embeddings); // Tensor of shape [2, 768] const matryoshka_dim = 512; embeddings = layer_norm(embeddings, [embeddings.dims[1]]) .slice(null, [0, matryoshka_dim]) .normalize(2, -1); console.log(embeddings.tolist()); ``` ## Nomic API The easiest way to use Nomic Embed is through the Nomic Embedding API. Generating embeddings with the `nomic` Python client is as easy as ```python from nomic import embed output = embed.text( texts=['Nomic Embedding API', '#keepAIOpen'], model='nomic-embed-text-v1.5', task_type='search_document', dimensionality=256, ) print(output) ``` For more information, see the [API reference](https://docs.nomic.ai/reference/endpoints/nomic-embed-text) ## Infinity Usage with [Infinity](https://github.com/michaelfeil/infinity). ```bash docker run --gpus all -v $PWD/data:/app/.cache -e HF_TOKEN=$HF_TOKEN -p "7997":"7997" \ michaelf34/infinity:0.0.70 \ v2 --model-id nomic-ai/nomic-embed-text-v1.5 --revision "main" --dtype float16 --batch-size 8 --engine torch --port 7997 --no-bettertransformer ``` ## Adjusting Dimensionality `nomic-embed-text-v1.5` is an improvement upon [Nomic Embed](https://huggingface.co/nomic-ai/nomic-embed-text-v1) that utilizes [Matryoshka Representation Learning](https://arxiv.org/abs/2205.13147) which gives developers the flexibility to trade off the embedding size for a negligible reduction in performance. | Name | SeqLen | Dimension | MTEB | | :-------------------------------:| :----- | :-------- | :------: | | nomic-embed-text-v1 | 8192 | 768 | **62.39** | | nomic-embed-text-v1.5 | 8192 | 768 | 62.28 | | nomic-embed-text-v1.5 | 8192 | 512 | 61.96 | | nomic-embed-text-v1.5 | 8192 | 256 | 61.04 | | nomic-embed-text-v1.5 | 8192 | 128 | 59.34 | | nomic-embed-text-v1.5 | 8192 | 64 | 56.10 | 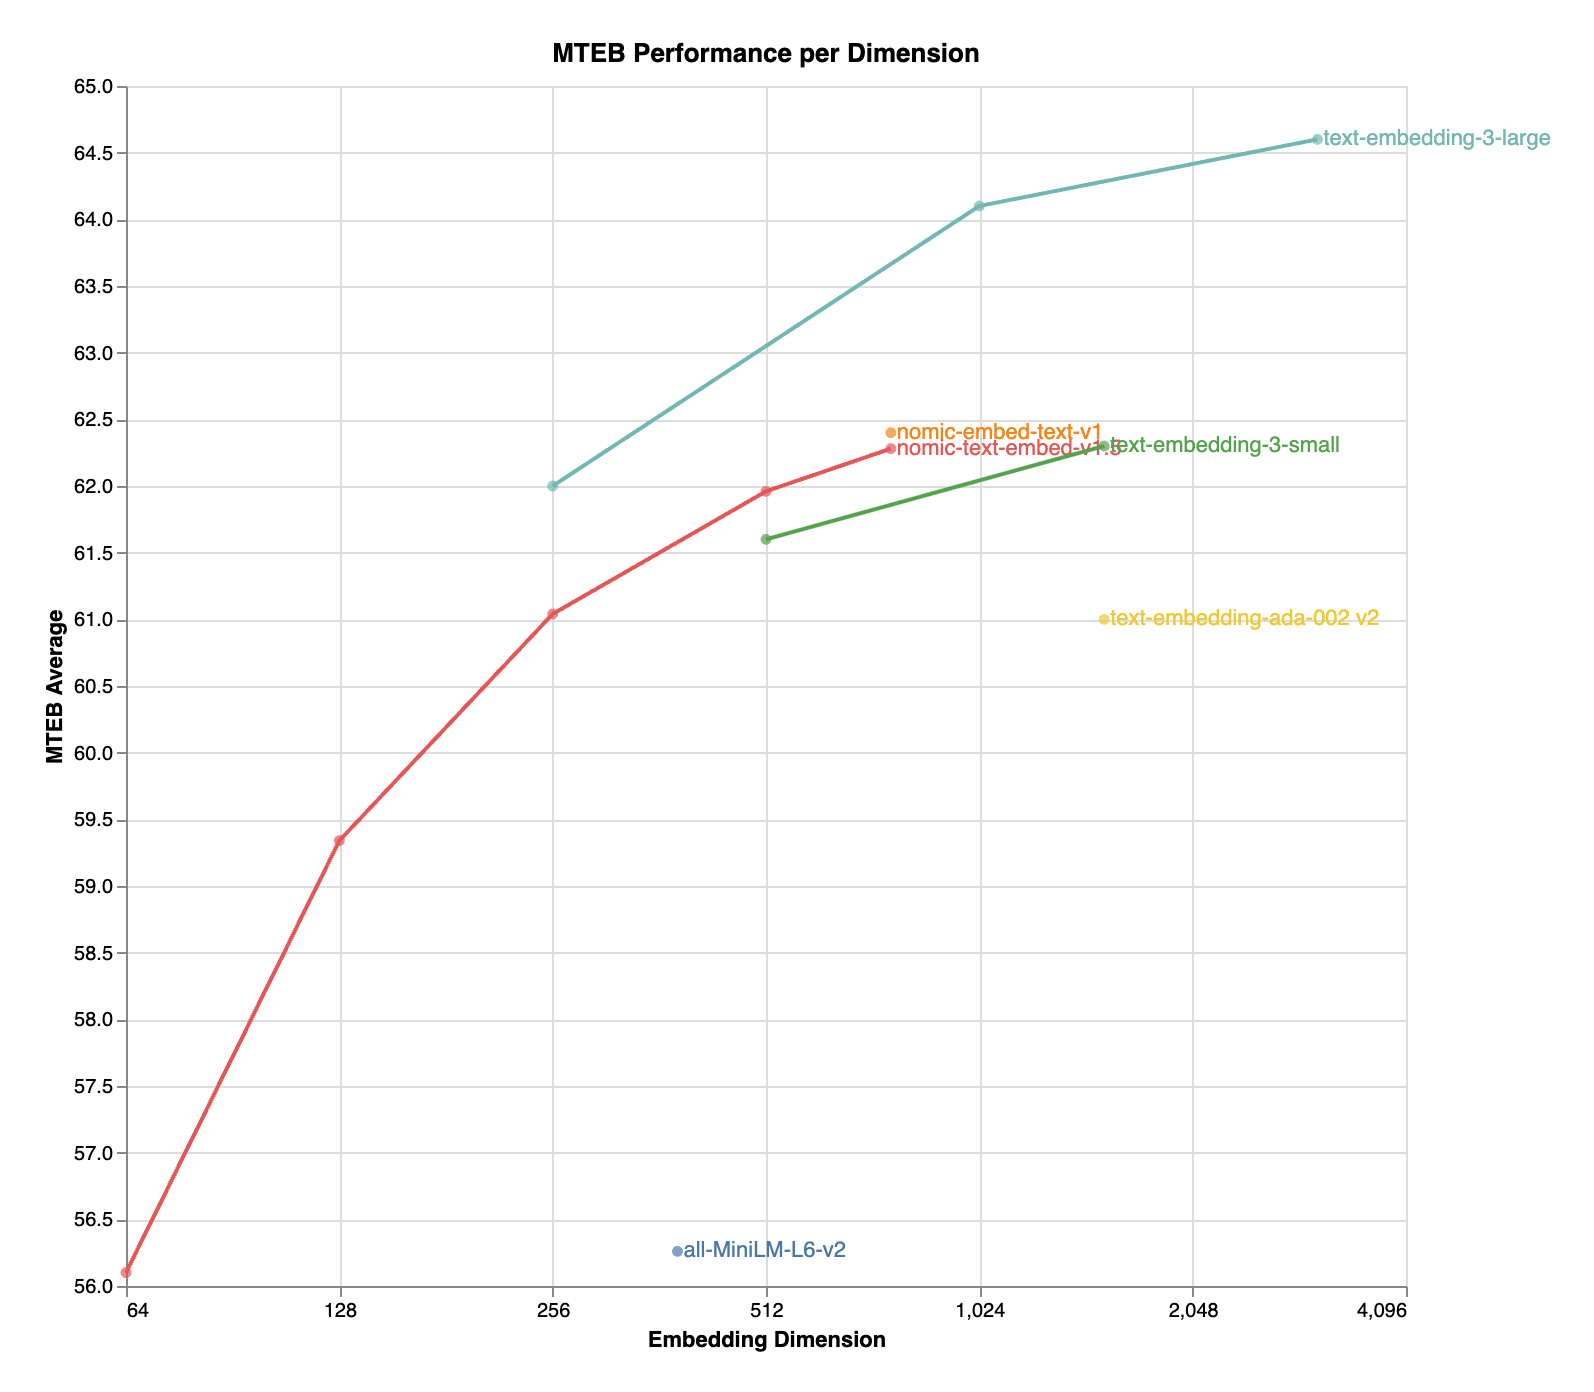 ## Training Click the Nomic Atlas map below to visualize a 5M sample of our contrastive pretraining data! [](https://atlas.nomic.ai/map/nomic-text-embed-v1-5m-sample) We train our embedder using a multi-stage training pipeline. Starting from a long-context [BERT model](https://huggingface.co/nomic-ai/nomic-bert-2048), the first unsupervised contrastive stage trains on a dataset generated from weakly related text pairs, such as question-answer pairs from forums like StackExchange and Quora, title-body pairs from Amazon reviews, and summarizations from news articles. In the second finetuning stage, higher quality labeled datasets such as search queries and answers from web searches are leveraged. Data curation and hard-example mining is crucial in this stage. For more details, see the Nomic Embed [Technical Report](https://static.nomic.ai/reports/2024_Nomic_Embed_Text_Technical_Report.pdf) and corresponding [blog post](https://blog.nomic.ai/posts/nomic-embed-matryoshka). Training data to train the models is released in its entirety. For more details, see the `contrastors` [repository](https://github.com/nomic-ai/contrastors) # Join the Nomic Community - Nomic: [https://nomic.ai](https://nomic.ai) - Discord: [https://discord.gg/myY5YDR8z8](https://discord.gg/myY5YDR8z8) - Twitter: [https://twitter.com/nomic_ai](https://twitter.com/nomic_ai) # Citation If you find the model, dataset, or training code useful, please cite our work ```bibtex @misc{nussbaum2024nomic, title={Nomic Embed: Training a Reproducible Long Context Text Embedder}, author={Zach Nussbaum and John X. Morris and Brandon Duderstadt and Andriy Mulyar}, year={2024}, eprint={2402.01613}, archivePrefix={arXiv}, primaryClass={cs.CL} } ```原始来源:https://huggingface.co/nomic-ai/nomic-embed-text-v1.5/blob/main/README.md